
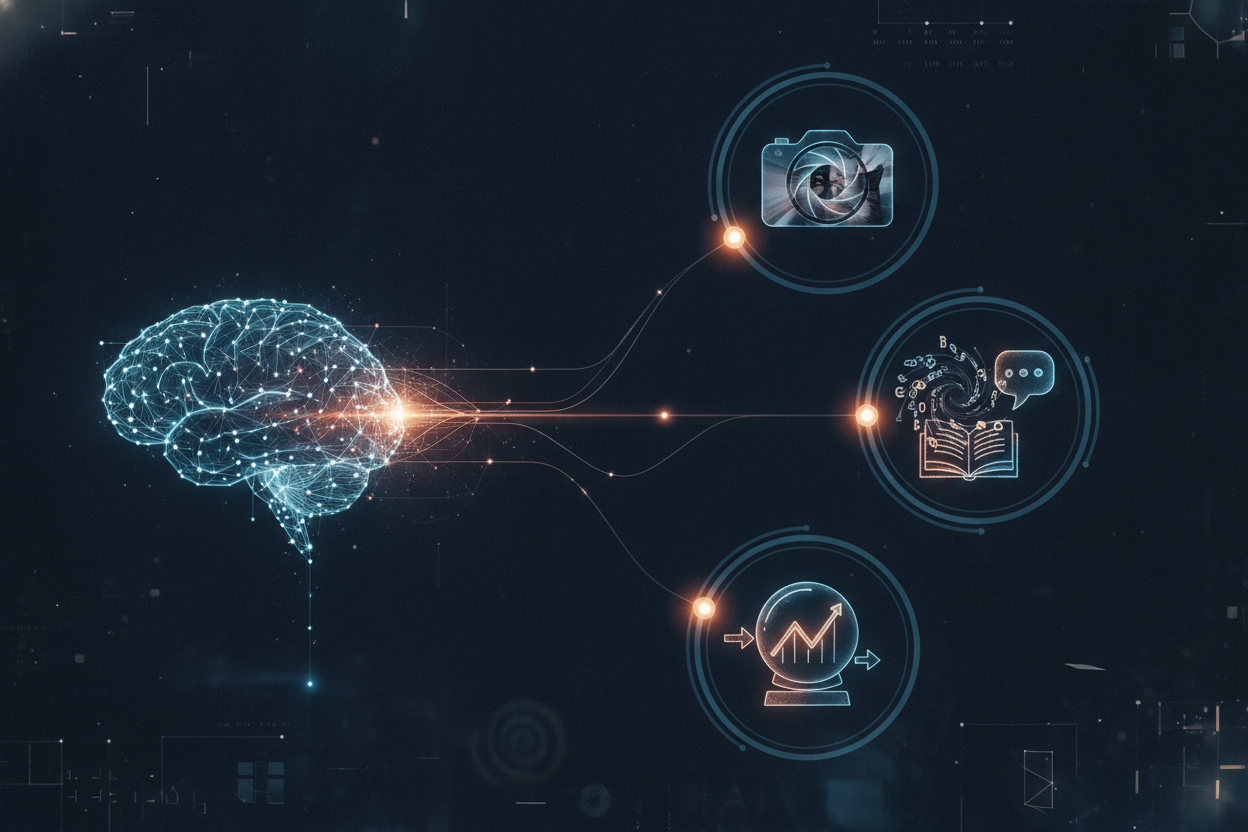
Neural networks often sound intimidating, but the core idea is simple: they are systems inspired by how the brain processes information. In practice, they are layered mathematical models that learn patterns from data. That ability makes them central to many modern AI applications, from image recognition to language processing.
A neural network starts with input data, passes it through layers of interconnected units, and produces an output. During training, the model adjusts its internal weights to reduce error. Over time, it becomes better at recognizing structure in the data. The more complex the task, the more layers and parameters may be needed, although more size does not always mean better performance.
What makes neural networks powerful is their flexibility. They can learn non-linear relationships that traditional methods may miss, especially when working with unstructured data such as images, audio, or text. That said, they also require more data, more compute, and careful tuning. Without good training practices, they can overfit or behave unpredictably.
For learners, the best way to understand neural networks is to start small. Focus on the concept of input, hidden layers, and output before diving into advanced architectures. Once the basics are clear, it becomes easier to see how deep learning systems are built and why they have changed so many fields.
Leave a Reply